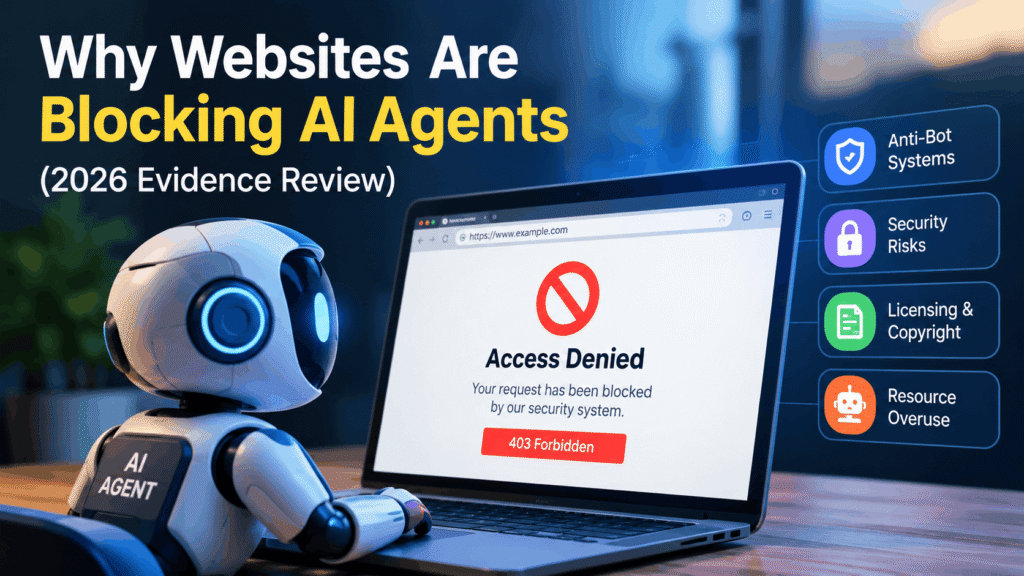

Why websites are blocking AI agents became a headline question in September 2026, when Amazon shut Meta’s Muse shopping agent out of Amazon.com less than two weeks after Muse launched. Meanwhile, Walmart, a Muse partner, watched its own anti-bot check trip the agent up by accident.
Two opposite motives. One result: an assistant that can’t finish its job.
So what’s really going on, and can autonomous AI ever work at scale? I went through court rulings, Cloudflare’s September policy changes, and a new university study to find out. The answer isn’t the one most headlines give you. (Hang tight. The twist comes in section two.)
What does it mean when a website blocks an AI agent?
AI agent blocking is when a website uses robots.txt rules, bot-management tools, terms of service, paywalls, or human-verification checks to stop software that acts for a person, such as a browsing assistant or shopping agent. Sites do it to protect security, ad revenue, licensed data, and customer relationships. It works by spotting automated traffic through user-agent strings, browser fingerprints, behavior, and challenge pages.
Why do websites block AI browsing agents?
Websites block AI browsing agents for four reasons: security, money, data control, and ownership of the customer. Often it’s a mix. Sometimes it’s an accident.
Start with scale. Thales’ 2026 Bad Bot Report found that automated programs generated 53% of web traffic in 2025, and 40% of all traffic was classified as bad bots. HUMAN Security measured traffic from AI agents and agentic browsers up 7,851% year over year. “AI-driven traffic is no longer experimental,” said HUMAN CEO Stu Solomon. Sites that spent a decade learning to distrust bots now face one that behaves like a customer.
Then follow the money. Cloudflare’s September 15 update presets ad-supported sites to block agents on pages with ads, because an agent loads the page while nobody is there to see the ad. Yelp told TechCrunch it admits agents only through its paid data-licensing program. Amazon says unauthorized agents bypass its personalization and raise privacy risks, yet it sells its own “Buy for Me” agent that shops other stores.
Notice the pattern? Security is the stated reason. Control is the pattern.
But here’s where it gets interesting. Some of these blocks weren’t decisions at all.
Are websites blocking AI agents on purpose or by accident?
Both, and the accidental half is the hidden problem. Plenty of blocks are side effects of anti-bot tools doing exactly what they were configured to do.
Take Walmart. TechCrunch reported that shoppers couldn’t complete purchases through Muse, yet Walmart said the failures weren’t intentional because it’s a Muse partner. The culprit was a button that must be clicked to prove you’re human. If an agent interrupts that check, it fails. One shopper complained on X that he couldn’t even sign in himself. Humans got caught in the net, too.
It’s not rare. Research from US Tech Automations, cited by CMSWire, found that 19.1% of the top 100,000 websites block at least one of 21 major AI crawlers in robots.txt. CMSWire’s list of accidental causes reads like a sysadmin’s confession: legacy bot rules, CDN defaults, rate limits, stray meta tags, JavaScript-only pages.
And the tools keep shifting under site owners’ feet. On September 15, Cloudflare retired its old “Block AI Bots” switch. Sites that had it on now disallow AI training and block agents on pages with ads, with no extra click. (Cloudflare told TechCrunch it had no specific data on whether this is breaking Muse traffic, so treat the link as suspected, not proven.)
Why can’t sites just tell agents “no” in robots.txt? Because the rules are inconsistent. Cloudflare itself says the internet has no well-established way to express that preference for agents. Per a June 2026 summary of vendor documentation, OpenAI says robots.txt may not apply to ChatGPT-User, Perplexity says Perplexity-User generally ignores it, and Anthropic says blocking Claude-User does stop its fetches.
Can AI agents bypass CAPTCHAs and anti-bot systems?
Yes, but usually with outside help. Paid solver services beat challenge-style CAPTCHAs nearly every time, while off-the-shelf AI agents mostly fail on their own.
Researchers at Florida International University tested seven commercial solver services and six LLM-based browser agents against hCaptcha, reCAPTCHA, and Cloudflare Turnstile. The solvers achieved near-perfect bypass on challenge-based CAPTCHAs for as little as $0.10 per 1,000 solves. Against reCAPTCHA v3’s silent scoring, they averaged only 23%.
The agents’ failure wasn’t about intelligence. Two agents with nearly identical click-and-type patterns got opposite results, and only the one running inside a real browser profile with cookies and history passed. The authors say the true boundary is “environment authenticity,” meaning whether the browser looks lived-in.
Here’s the quick comparison:
| Defense | How it works | Where it breaks |
|---|---|---|
| CAPTCHA challenge | Puzzle or checkbox | Cheap solver services pass it |
| Risk scoring (reCAPTCHA v3, Turnstile) | Silent browser and behavior signals | Flags clean, automated browsers |
| Agent identity (Web Bot Auth) | Agent signs each request cryptographically | Still an IETF draft; sites must choose to trust it |
| Licensing or payment | Contract or paid access | Needs a deal for every site |
Honestly? I think the CAPTCHA is on its way out for this job. The question has changed from “are you human?” to “whose agent is this?” The U.S. government sees it the same way: NIST’s AI Agent Standards Initiative, launched February 17, 2026, researches agent authentication and identity infrastructure.
The next part matters most, because it decides whether any of this changes your business.
Will autonomous AI shopping and browsing work at scale?
Not yet. AI already influences a big slice of online spending, but agents completing purchases on their own remain a small share.
The State of AI Report from Air Street Capital notes that AI and agents influenced roughly 20% of global online holiday spending in 2025, about $262 billion. Yet as of July 2026, no major retailer had reported more than 5% of online sales through agentic checkout. Influence isn’t delegation. One 2026 roundup found only 14% of consumers willing to let an agent buy unsupervised, and noted that forecasts differ by a factor of 240 depending on what counts as “agentic.”
Forecasters stay bullish anyway. Commercetools’ 2026 guide cites a projection that nearly half of online shoppers will use AI agents by 2030, covering about 25% of their spending.
Then there’s the law. On August 4, 2026, the Ninth Circuit lifted an injunction that barred Perplexity’s Comet browser from shopping on Amazon, reasoning that the user, not Perplexity, accesses the site. The court found Amazon unlikely to win its anti-hacking claim under the Computer Fraud and Abuse Act, but it limited the ruling to the record before it, and the underlying lawsuit continues. Amazon’s Muse popup leans on its Conditions of Use, not a hacking claim.
My contrarian take: blocking won’t stop agentic commerce, but it will decide who controls it. Meta put the stakes bluntly: “Turning away a personal agent means turning away the customer behind it.” Meta, Walmart, Stripe, and others are now drafting an open standard for how agents talk to businesses.
How do you decide whether to block, allow, or charge AI agents?
Sort agent traffic by what it’s doing, pick a policy for each behavior, and verify identity instead of guessing. Here’s a five-step framework you can run this week.
- Audit what’s blocked right now. Check your CDN or firewall, robots.txt, rate limits, and meta tags. On Cloudflare, review the September 15 migration, because your old settings may now mean something different.
- Split traffic into three behaviors. Cloudflare sorts bots into search, training, and agent. A site can welcome search, refuse training, and treat agents case by case.
- Choose allow, block, or charge for each behavior. Ad-funded publishers often block agents on ad pages. Retailers may allow agents that identify themselves. Data-rich sites can license access, as Yelp does.
- Ask agents to prove who they are. Verify signed requests where you can, and publish agent terms. Amazon’s terms require agents to identify themselves and stop when asked.
- Name an owner and retest monthly. Blocking carries commercial consequences, so someone accountable for revenue should own the policy.
Hang tight, because the next section is where this framework gets tested.
Who benefits from letting agents in, and when should you still block?
Retailers, booking sites, and service businesses with clear catalogs benefit most, because an agent’s visitor already knows what they want. Cloudflare reports that consumers referred by AI search convert at three to over five times the rate of traditional search referrals. Fewer visits, more intent.
Picture a mid-size online retailer. A verified agent arrives, reads structured product data, and checks out. No window-shopping, no abandoned cart. That’s the best case.
When should you still block? If your revenue depends on ad impressions, your content sits behind a paywall, or your account pages hold personal data, default to blocking with exceptions. Delta told TechCrunch that any opening to agents would need security and the customer experience in mind.
This won’t fit everyone, and your mileage may vary. [Add one real first-hand example here: a time an agent was blocked on your site, or a bot rule you changed and what happened.]
FAQs
Is it legal for an AI agent to use a website on my behalf?
Often, but contract terms still matter. On August 4, 2026, the Ninth Circuit found Amazon unlikely to win its anti-hacking claim against Perplexity because the user accessed the site. The court limited its ruling to that record, and terms-of-service claims continue. This isn’t legal advice.
Does robots.txt stop AI agents?
Not reliably. It only works on agents that choose to obey, and vendors treat user-triggered fetchers differently. Pair robots.txt with firewall rules and verified-agent checks, then retest monthly.
What is Web Bot Auth?
Web Bot Auth is a draft IETF protocol that lets AI agents cryptographically sign HTTP requests so websites can verify who is calling. Amazon’s Bedrock AgentCore Browser supports it in preview to reduce CAPTCHA challenges.
Which websites block AI agents?
Users report blocks at Amazon, Yelp, eBay, Zillow, Pizza Hut, Adidas, and several airlines. Some are deliberate, others are anti-bot side effects. Walmart says its Muse problems were unintentional, and Zillow says it allows consumer agents but anti-scraping tools sometimes catch them.
Will blocking AI agents hurt my Google rankings?
Not if you block the right bot. Cloudflare says under 1% of its sites block search bots, and it notes Google states that disallowing Google-Extended doesn’t affect search ranking. Blocking Googlebot itself would.
Can I charge AI agents for access?
Yes. Cloudflare runs a marketplace where AI bots pay for content, and Yelp admits agents only through paid data licensing. Expect more pay-per-access deals as identity standards mature.
What to do next
Here’s what matters after all that reading. First, blocking is usually about money or control, and a surprising amount is accidental. Second, CAPTCHAs are a speed bump, while verified identity is the lock. Third, agent shopping is real but nowhere near scale.
Whether you run a store or build agents, why websites are blocking AI agents comes down to trust, and trust needs identity.
Do this today: open your bot settings and check which AI agents you’re blocking by mistake. Then share what you find in the comments.